For years, conversations about trustworthy artificial intelligence have centered on making models smarter, more accurate, or better aligned. Those goals matter, but they do not solve the central problem of enterprise AI: who is responsible when an autonomous system makes a consequential decision?
A model can generate an answer. It cannot assume legal, ethical, or institutional responsibility for that answer. That obligation belongs to people and organizations. This is why trustworthy AI begins with accountable humans, not improved models.
Accountability must be an operating mechanism. In practical terms, every deployed agent should have a named business owner, a defined authority boundary, an evidence standard, an escalation route, and an audit trail. Before giving an agent access to a system, executives should be able to answer five questions: What may it do? Based on what evidence? Which rules constrain it? Who approves exceptions? Who is responsible for its outcomes? If those answers are missing, the organization has not delegated responsibly; it has simply automated ambiguity.
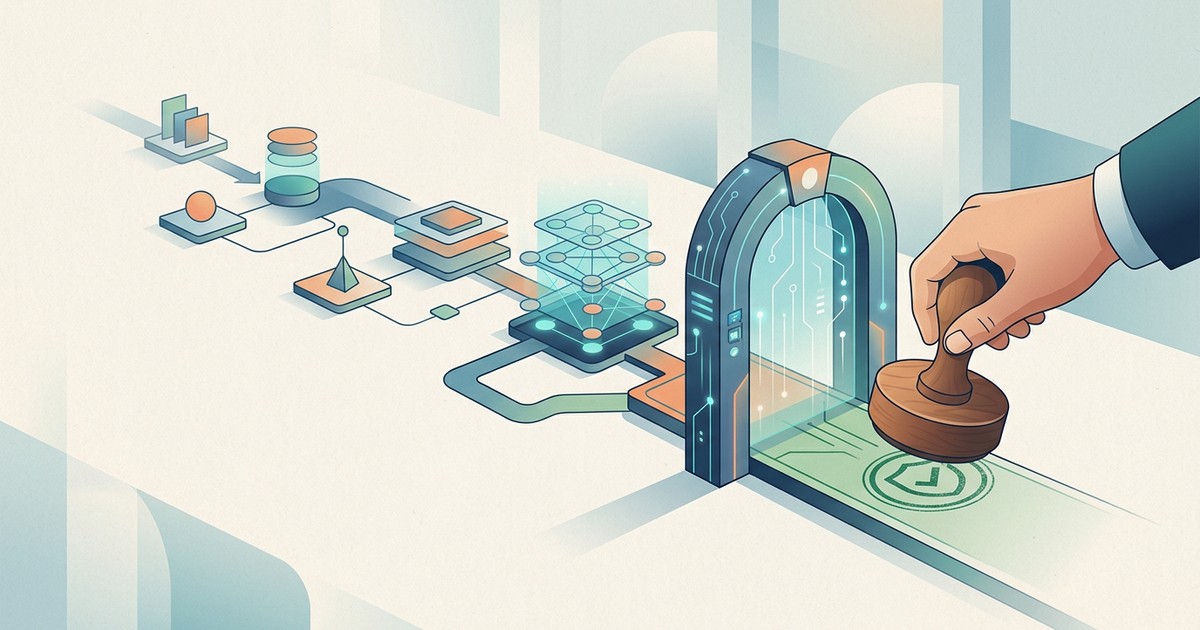
At QGI, our design philosophy is that generative intelligence should propose, but independent controls must decide whether a proposed action is permissible. We describe the pattern as Assume → Verify → Prove → Act. The AI proposes a plan and identifies its assumptions. An evidence layer validates factual claims against authoritative records. A deterministic policy verifier checks that the proposed action satisfies applicable rules. An execution gateway authorizes only actions that pass. A violation is blocked; an unknown result is escalated. In this architecture, a persuasive explanation is never a substitute for verified authorization.
Why do impressive agent demos so often fail in production? A demonstration typically operates on clean data, predictable prompts, oversimplified assumptions and known permissions. Production introduces missing documents, contradictory sources, shifting regulations, partial outages, ambiguous identities, relaxed permissions and humans who may have conflicting objectives. Technical failures include unreliable tool calls, state drift, incorrect retrieval, and fabricated certainty. Organizational failures are equally serious: no process owner, unclear exception handling, incompatible incentives, and pressure to treat a pilot as proof of operational readiness. The demo shows that a task can be completed. Production requires evidence that it can be completed safely, repeatedly, and with a recoverable failure path.
That is why permissions, escalation and accountability must precede deployment. Each agent needs least-privilege credentials, narrowly scoped tools, explicit limits on transactions and data access, reversible operations where possible, and logging that reconstructs what the system knew at the moment of action. There must be a clearly defined path from an unresolved uncertainty to a qualified human reviewer. Teams frequently skip these controls because they make launch slower. But they are the difference between an experiment and an institutionally reliable system.
Human judgment must remain mandatory when the decision involves contested values, exceptional circumstances, or irreversible consequences. Consider lending. An AI can extract documents, calculate ratios, compare requirements, and assemble a reasoned recommendation. But a decision involving exceptions, possible discrimination, material missing evidence, or a disputed adverse outcome requires accountable governance and, where appropriate, qualified human review. In regulated settings, the critical question is not whether the model sounds confident. It is whether the decision complies with the governing rules and can be explained from the actual evidence.
Our work on deterministic lending illustrates the distinction. Instead of letting a language model interpret an underwriting rationale, policy rules can be versioned and evaluated deterministically or escalated to a human. Each outcome can then trace back to the facts and rule versions used, supporting review and applicable notice requirements. The model helps people navigate complexity; it does not get to rewrite the rules silently.
Who owns a technically correct but ethically risky outcome? Ultimately, the accountable executive and the institution deploying the system. Technical correctness is not the same as legitimacy. A model could optimize a narrow objective while disadvantaging customers or undermining trust. Product teams should therefore identify prohibited outcomes and governance constraints before optimization begins. Risk and compliance functions need authority to halt a deployment, not merely advise after the fact.
As AI use grows, informal oversight stops working. A small experiment may be managed by its product owner. A portfolio of agents with access to customers, money, records, and business operations requires a formal registry of deployed agents; classification by risk; policy and model versioning; independent testing; incident response; and periodic review of whether each delegation remains justified. Oversight should scale with the potential harm of each action, rather than impose identical friction on everything.
The biggest bottleneck is not model capability alone. It is leadership's willingness to specify ownership, accept the cost of controls, and constrain automation where the risk is unacceptable. A company that celebrates autonomy but cannot identify who is accountable for an agent's actions is not ready to scale it.
Measure trust in production, not just model benchmarks. Useful metrics include the share of consequential actions backed by verifiable evidence, policy violations blocked before execution, uncertainty escalated appropriately, mean time to detect and recover from errors, unauthorized actions, and the ability to reconstruct decisions under audit. An agent's raw task-completion rate may improve even while its risk profile deteriorates. Trustworthiness is a property of the humans-plus-system arrangement, not a single model score.
My experience also spans physical laboratories. At Qalitex, operating in environments shaped by quality standards makes the lesson concrete: reproducibility, traceability, defined procedures, and corrective action matter as much as clever analysis. AI can accelerate documentation, help coordinate workflows, and surface relevant knowledge. Yet adoption is slower wherever source data are fragmented, responsibilities are unclear, or a result cannot be independently verified. Those limits should inform design, not be concealed in marketing.
For executives who have only 90 days to improve accountability around an existing AI deployment, I recommend three moves. First, inventory every agent and the systems it can access; assign one human owner and a risk classification to each. Second, put the highest-risk actions behind explicit policy gates, evidence checks, and an escalation mechanism. Third, run realistic failure tests and produce an auditable record of decisions, exceptions, and corrective actions. This foundation can be built incrementally, but it should begin immediately.
My book, The Singularity of Hope, considers humanity's place in an AI-dominated future. Over the next two years, leaders must do something models cannot do on their behalf: choose the values, legitimate boundaries, and responsibilities that will govern powerful systems. AI can expand the range of possible actions. Humans must decide which actions deserve to be taken, who has authority to take them, and who answers when things go wrong.
The future of trustworthy AI will not be secured by the most impressive demo. It will be secured by institutions capable of saying, clearly and credibly: here is the evidence, here is the rule, here is the accountable decision-maker, and here is how we can correct a mistake.